Mixture of Experts: how an AI model fires only the right experts
For years the intuition about AI models was simple: bigger means smarter. But there is a hidden cost, because every answer lights up the entire model even for the most trivial question. Mixture of Experts breaks that link: it splits knowledge into many specialized sub-networks and activates only a few at a time, chosen by an internal router. So a model can be huge in total knowledge and light in what it uses per answer. Yet it stays one model, with one view of the problem: the router picks among experts that share the same training. For decisions that matter, the limit is not efficiency, it is the single perspective, and that is the jump that leads to Arena.
by Redazione AI Arena
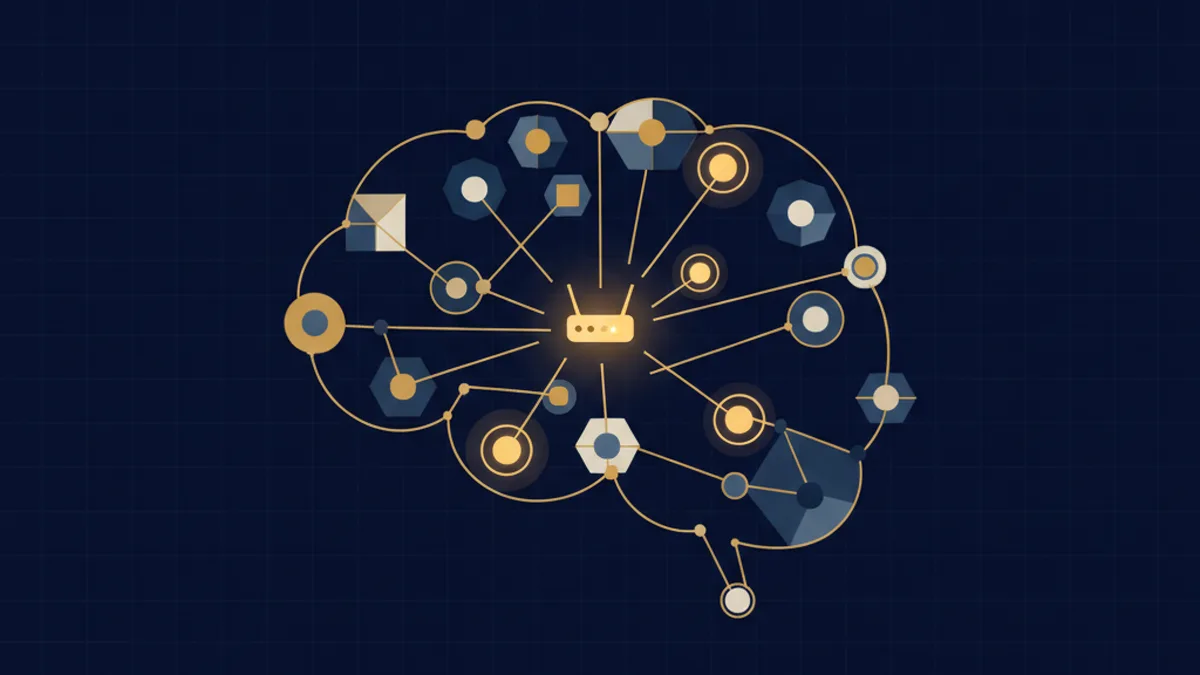
For years the dominant intuition about AI models was simple: bigger means smarter. Add parameters, and the model can do more. But hidden inside this race for size is a cost that rarely gets told: every time the model answers it uses all of itself, every single parameter, even for the most trivial question. It is like powering up an entire factory to turn one screw. Mixture of Experts, often shortened to MoE, was born precisely to break this link between size and cost — a model can be enormous in total knowledge and light in what it actually activates on each answer.
A model that does not use all of itself every time
The core idea of Mixture of Experts is to split the model's knowledge into many specialized sub-networks, the experts, and put to work only the ones needed for a given request. It is not a set of separate models: it is a single model inside which many blocks coexist, each having become good at a slice of the work during training. One may have tuned itself to code, another to a certain kind of reasoning, another to a particular nuance of language — though in practice these specializations are fuzzier and less readable than the way we describe them in words.
When a request arrives, the model does not call every expert. It selects a small subset, the most relevant ones, and leaves the others off. The result is that a model with enormous overall capacity, on the single answer, brings only a fraction of it into play. Total knowledge stays large; the bill to pay on each question stays small. This is the move that makes MoE so interesting: it decouples how much a model knows from how much it costs to use.
The router that decides who works
The piece that holds it all up is the router, sometimes called gating: a small internal mechanism that, for every incoming piece of text, decides which experts to pass it to. It is not a rule hand-written by an engineer, it is something the model learned along with everything else during training. Over time the router learns that a certain kind of input works better when routed toward certain experts, and it sharpens that choice with every pass.
This routing is the most delicate part of the architecture. If the router almost always sends everything to the same two or three experts, the others stay useless and the extra capacity is wasted; if it distributes at random, it loses the benefit of specialization. That is why training an MoE requires techniques that keep the load balanced, so that all experts get used and none becomes a bottleneck. It is worth pausing on one point, because it is what really matters further on: even when routing works perfectly, there is still a single model deciding how to read the problem. The router picks among experts that share the same training and the same view of the world. It is internal efficiency, not a plurality of perspectives.
Power without paying the full bill
The reason Mixture of Experts has become central in recent models is practical before it is theoretical. It lets you grow a system's overall knowledge — more experts, more skills covered — without growing the cost and slowness of each answer in proportion. It is a way around the trade-off between quality and speed that would otherwise force a choice: either a big slow model or a small fast one. With MoE you try to have both, breadth of skill and lightness on the single answer.
From here a broader shift in the direction of AI emerges. For years size was chased as the only lever; today research is moving toward how to organize that size — which parts to activate, when, by what criterion. MoE is one of the first signals of this maturity: a bigger brain is not enough, you need a brain that knows how to use the right part of itself at the right moment. It is a principle that resembles how complex systems work in general, where intelligence lies not only in the individual components, but above all in how they are coordinated.
Where the world is heading, and Arena as the natural conclusion
Mixture of Experts solves an efficiency problem inside a single model: how to deliver plenty of skill without paying for it in full on every answer. But it stays, precisely, inside one model — one training, one setup, one idea of what counts in a problem. The experts the router selects are variations of the same mind, not different points of view. For many requests this is more than enough. For decisions that matter, it is not: there the limit is not efficiency, it is the single perspective.
And that is exactly the jump that leads to Arena. AI Arena is the platform that compares several AI identities with different perspectives on the same problem, lets you select the most useful answers, and uses an Orchestrator to carry you to the next step; it does not replace your decision, it helps you make it with more awareness. If MoE picks experts inside a single head, Arena compares different heads: you pick the team, bring your question, and 7 complementary specialists each write their own reading, with complementary perspectives that a single model — however well routed — cannot have on its own. You select what holds up, the system refines and deepens, and the Orchestrator, the meta-layer that keeps the flow together, guides you all the way to the final report. The internal efficiency of one model is one thing; the comparison between different views is another, and for the choices that weigh it is what makes the difference.
Join Arena.
FAQ
What is Mixture of Experts in an AI model?
Mixture of Experts, often shortened to MoE, is a way to build an AI model by splitting its knowledge into many specialized sub-networks, called experts, instead of keeping it in one undifferentiated block. These are not separate models bolted together, but a single model inside which many experts coexist, each having become good at a slice of the work during training. The key trait is that, for every request, the model activates only a small subset of experts and leaves the others off. So the total knowledge can be enormous, while what the model actually uses on any single answer stays a fraction of it.
How does an MoE model choose which experts to use?
The job falls to an internal component called the router, or gating. For each piece of incoming text, the router decides which experts to send it to, routing the request toward the most relevant ones. This is not a hand-written rule: it is something the model learned during training, along with everything else. Over time the router learns that certain kinds of input work better when sent to certain experts. It is the most delicate part of the architecture, because if it always routed everything to the same experts the extra capacity would be wasted, and if it distributed at random it would lose the benefit of specialization.
Why does Mixture of Experts make a model more efficient?
Because it separates the overall size of the model from the cost of each single answer. In a traditional model every parameter is used on every request, so growing the knowledge means growing cost and slowness in proportion. With MoE you can add experts, and therefore skills, without activating them all at once: on each answer only the selected part works. It is a way around the trade-off between quality and speed that would otherwise force a choice between a big slow model and a small fast one.
Is a Mixture of Experts model the same as using several AI models together?
No, and the distinction matters. In an MoE the experts are parts of a single model, born from the same training and with the same underlying setup: the router picks among variations of the same mind, not among different points of view. It is internal efficiency, not a plurality of perspectives. Using several different AIs together is another thing: it means comparing distinct identities, trained and configured differently, that read the same problem from genuinely different angles. MoE optimizes how a single model uses itself, while comparing several AIs adds the variety of views a single model cannot have.
How does Mixture of Experts connect to comparing several AIs in Arena?
AI Arena is the platform that compares several AI identities with different perspectives on the same problem, lets you select the most useful answers, and uses an Orchestrator to carry you to the next step; it does not replace your decision, it helps you make it with more awareness. MoE solves an efficiency problem inside a single mind, choosing which experts to activate, but it stays one perspective. Arena works at the layer above: you pick the team and 7 complementary specialists each write their own reading, with complementary perspectives a single model cannot have. You select what holds up, the system refines and deepens, and the Orchestrator keeps the flow together all the way to the final report.
Topics